
How Tasadr works, how we measure your AI visibility
We ask up to 8 AI engines, by plan, your customers' questions in their own words, and record where your site stands in every answer: the Tasadr (تصدَّر) score out of 100, with each answer's excerpt as evidence. Measuring starts the journey; then we diagnose who leads instead of you, recommend fixes, check the edit and measure its impact.
Last updated:
Real report · names hidden · measured 12 to 26 Oct 2026
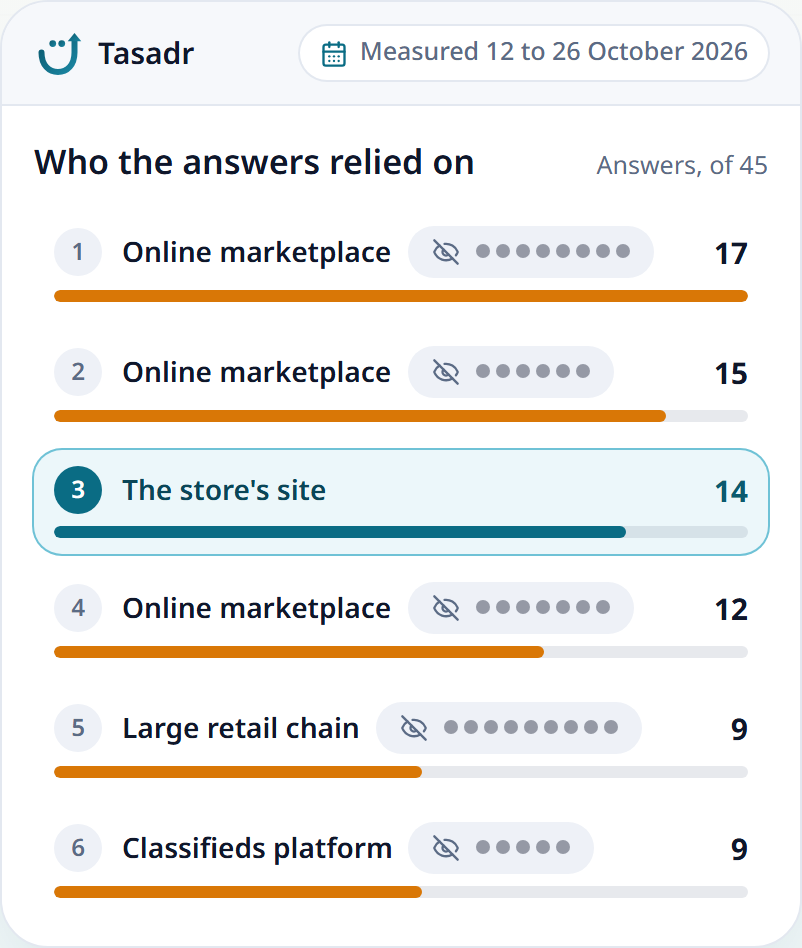
From an analysis we ran on the site of an electronics and home-appliance store in Egypt, putting 15 questions in its buyers' own words to 3 AI engines. We hid every site's name and wrote its kind beside it.
Read the full report of this measurementThe question
What do we ask the engines?
We ask your customers' questions in their own wording: a full sentence in your market's language, not a keyword. The question is the unit here, because an engine answers questions and does not rank words.
Every site carries its own country, set before the first measurement. The country changes the answer: a customer in Riyadh and a customer in Dubai ask in different words, and Google's AI answers differ from one country to the next. So your questions are written for your market, Google's answers are read as they appear in your site's country, and what you get is your market rather than a generic version.
Questions come from three places, and you can mix them. Start with buying questions from a customer close to deciding, not general questions about your industry. Choosing the questions worth measuring works through it with examples.
You write them
the questions you hear in sales and support every week.
We find them in your question gap
questions your competitors lead that you do not track yet, to add the ones that matter to your measurement.
We suggest them from Google Search Console
real searches that already reach your site, if you connect it, and from your pages when it is not connected or you start from nothing.
The engines
Which engines do we ask?
We ask 8 engines: ChatGPT, Google AI Overviews, Gemini, Perplexity, Google AI Mode, Copilot, Claude and Grok. How many a measurement uses follows your plan, and the 7-day free trial starts with 2, ChatGPT and Gemini.
They fall into two kinds, and the difference is how your customer reaches them:
Chat engines
 ChatGPTIn the trial
 GeminiIn the trial
 Perplexity
 Claude
 Grok
Chat engines, being ChatGPT, Gemini, Perplexity, Claude and Grok: your customer opens them and asks, and the answer moves between one ask and the next.
Search surfaces
 Google AI Overviews
- Google AI Mode
 Copilot
Search surfaces, being Google AI Overviews, Google AI Mode and Copilot: they reach your customer mid-search, inside the results page itself, in Arabic and in their country.
That difference is not a detail. A chat engine answers one person in one moment; a search surface shows the same page to everyone who searched that hour. What sets each engine apart is in the engines we measure, and which your plan includes is in Tasadr plans and prices. How each engine picks its sources is in the ChatGPT guide in Arabic and the guide to Google AI Overviews in Saudi Arabia.
The cadence
How often do new results arrive?
We put every question to the engine afresh each time we measure it, so one lucky answer is never counted as a change. That is the difference between knowing what an engine said once and knowing what it usually says.
On every paid plan your dashboard updates every day, and the measurement runs without anyone pressing anything:
Free trial
two measurements in its 7 days, when setup is done and on day 5, once you prove the site is yours.
Starter, Pro and Advanced
updated daily, so your dashboard gets new results every day.
Business
updated daily, on up to 8 engines chosen with you.
What grows from one plan to the next is how many sites, questions and engines your daily results cover. After an edit, its effect is read in the analyses that follow. What each plan carries is set out in full on Tasadr plans and prices.
The four outcomes
What are the four outcomes per answer?
For every question on every engine we record one of four outcomes, and keep the excerpt of the answer that names you or your competitor, word for word as the engine wrote it, with the links it cited, so you can check it rather than believe us, as in a real report for an electronics store in Egypt:
Cited
Your site's link is among the answer's sources, with or without your name; the best outcome there is.
Mentioned
Your brand in the text, with no link to open.
Absent
An answer was written with neither your link nor your name.
No answer
The engine wrote nothing for that question in that measurement.
Never counted against your site
The score
What does the score out of 100 tell you?
The score is one number out of 100 saying where your site stands inside the engines' answers to your questions, per site. You read it in a line, then read under it the question you won and the question you lost, because a single number hides both.
When a measurement spans a range, we show it beside the score: the lowest and highest figure in that measurement. A wide range means the number is less settled than it looks, and your decision needs that.
An engine that wrote no answer is never counted against your site. It chose nobody, and charging you for its silence would lower your number over an answer that was never written.
Under every verdict sits the evidence: the answer's excerpt, word for word as the engine wrote it, the links it cited, and the date. The score is not an opinion you take on trust, it is the summary of texts you can open and read yourself.
Confirmed change
When do we say something has changed?
When the change is confirmed, not on a single answer that carries it. The rule is written in advance and is the same for every account, so headlines and alerts do not flicker:
A new competitor
we do not call it new on a single answer; the change has to hold.
Once it holds
A lost citation
we do not report it lost on a single answer without it; the absence has to hold.
Once it holds
A new gain
counts at once, because a citation that happened has happened.
At once
What passes the rule reaches your dashboard as an alert; what does not stays in the history for you to read. So you never wake to an alert caused by one odd answer. Why answers change at all, and how to test it yourself, is in why ChatGPT's answers change, and when a change is real.
Competitors and the plan
Who was cited instead of you, and what do you do?
For every question we record who was cited instead of you and how often, then compare your page with theirs: what their page answers that yours does not. How many why-they-lead analyses you get follows your plan: one why-they-lead analysis in the free trial, then 15 why-they-lead analyses a month on Starter, 50 why-they-lead analyses on Pro, 100 why-they-lead analyses on Advanced, and no limit on Business.
The repeated gaps become an action plan ordered by priority: what to change first, on which page, and why. Ordered by expected effect rather than frequency, because one large question can be worth ten small ones.
The comparison itself is plain: your page and theirs side by side, and what each answers. We do not guess at the engine's hidden rules: we show what is on their page and missing from yours, and you decide which gap is worth an hour.
How to read that comparison and follow a competitor over time is in which competitor ChatGPT recommends instead of you. Everything you see about your competitors in your dashboard, from their ranking to each one's file, is on the competitor comparison page.
After the plan
What comes with each task, and how do you know it worked?
We do not stop at telling you what to change. Every why-they-lead analysis comes with on-page fixes, ready to publish. An answer paragraph that answers the question directly, an FAQ in your customers' words and structured data (schema) for your page. We write them from your page and your business profile alone, add no fact you did not give us, and label them a draft for you to review before publishing.
When you edit your page, the implementation check comes first: we check the edit is live on the page before we measure its impact. Then comes the impact, measured on the same questions, so any gain you see after your change follows work that was really done, not just a ticked box. The impact also compares the question you worked on with the questions you left untouched, over the same measurements. Why correct facts matter so much to a business customers visit in their own city is set out in local GEO: AI answers for local businesses. And with all of that:
Send the task
To a developer, an SEO lead or a content writer, and each gets only their part, copied, on WhatsApp or through a private link.
The weekly and monthly reports
Every week on the paid plans, what you gained, what threatens you and your next step, ready to copy to WhatsApp as it is, and every month a report of what changed in your standing, what you got done and your top tasks for the month ahead.
The executive summary
A private link to one page for your manager, with your score, your top competitors, the confirmed changes and the top three tasks, read without signing in.
Where the answers come from
The sites the engines build their answers to your questions from, grouped by kind, and what to do about each kind. From directories and platforms to forums and news sites, so you know where you need to be present for an engine to cite you.
A file on every competitor
Where they lead, with which pages and on which engines, and track them as a competitor from any screen that names them. It also lists the questions they lead that you do not track yet, so you can add the ones that matter to your measurement.
What sets Tasadr apart
How is Tasadr different from measurement tools?
We built our method on the Arabic question from day one. It has eight points, and their value is in the combination rather than in any one of them:
What we do
Questions in your customer's words, about their own market, not the language of your internal deck.
Google's answers as your customer sees them in their country, not a generic version of another market.
Repeated measurement that separates luck from fact, so one lucky answer is never counted as a change.
Text evidence under every verdict. The answer's excerpt, word for word, its sources, with its date.
An analysis that says why your competitor was cited, and what to change on your page.
An alert only when a change is confirmed, never an alert for every wobble.
Clear prices in US dollars, paid in your local currency in Egypt, Saudi Arabia, the UAE, Qatar and Morocco, with no per-question fees.
On-page fixes from your own facts alone, and an implementation check on the page before we measure the impact.
And what do we refuse to do?
We say this without naming anyone, because it describes what we chose rather than attacks what others sell:
- We do not hand you the engine's raw text and leave you to make sense of it alone.
- We do not meter you by prompt, so the bill is never a surprise.
- We do not measure an English-speaking market and call the result an Arab market.
- We do not give you a general number no decision can rest on.
- We do not write a fact into your on-page fixes that you did not give us.
The limits
What do we not measure, and what are the limits?
We say this early so you read the number for what it is: a high score does not guarantee visits, and a measurement is a picture of your questions, not a census of every conversation in the world.
For a picture of whole markets, we publish what we measure there, with its date, its scope and its data, in the Tasadr Observatory.
What we do not sell yet, we also say: no API. For another question about how Tasadr works or the plans, more than 30 answers sit in the questions people ask about Tasadr, and the field is defined in what GEO is.
The score is ours
computed from our own measurements by a fixed rule, and issued by no engine.
No citation is guaranteed
an engine picks its sources afresh every time, and nobody sells a place among the sources it cites.
We do not measure what you did not ask
widening the question list is what widens the picture.
We do not measure your traffic
we measure your place in the answer. Connect Google Search Console and we set your site's Google Search clicks beside your score, as Google counts them, including those from its AI answers, so we never present them as AI traffic.
Frequently asked questions
Can I change my questions after starting?
What does the range beside my score mean?
Can I measure more than one country?
Do I have to connect Google Search Console?
How do you measure what people call "AI visibility"?
Measure your site free for 7 days
Add your site, set its country, and read your first measurement with the answer excerpts and their sources. No credit card needed.